
SpaceX AI Unveils Grok 4.7: Flagship Generation for Coding and Knowledge Work Priced Same as Grok 4.6
TradingKey - SpaceXAI (SPXC's AI division, formerly xAI) released Grok 4.7 on September 21, officially positioning it as its most capable generation of models for coding and knowledge work to date. Pricing remains consistent with Grok 4.6: $2 per million input tokens and $6 per million output tokens. On CursorBench 4.0, which specifically evaluates long-duration coding tasks, Grok 4.7 scored 46.3%, 5.9 percentage points higher than Grok 4.6, with official claims placing it at the cost-performance frontier within its price tier on this benchmark.
Over the past two years, capability enhancements in flagship models have typically culminated in higher token unit prices: generational upgrades, price hikes, and then waiting for the industry to gradually absorb inference costs. Grok 4.7 takes a different path: while pushing capabilities higher, its pricing and inference speed remain at the level of Grok 4.6, along with an additional fast version that doubles the output speed.
Officially disclosed details focus on four aspects: changes in base model and reinforcement learning training, horizontal and vertical comparisons across seven benchmarks, cost structures under long-duration tasks, and a completely rewritten safety guardrail stack. In addition, effective immediately, the model is available simultaneously across Cursor, Grok Build, Grok API, and third-party coding frameworks and model routing platforms.
Grok 4.7's core value proposition centers on three capabilities: long-duration task coding, professional document generation, and safety guardrails. All three share the same pricing structure—offering the same price and speed as the previous generation—while using a fast version to cover latency-sensitive scenarios.
Official benchmarks indicate that progress in this generation of models is continuous: CursorBench 4.0 improved by 5.9 percentage points, Terminal-Bench 4.0 nearly doubled, AA Briefcase gained 111 points, and it achieved the company's highest score on biosecurity benchmarks. At the same time, the absolute level of 19.6% on legal benchmarks and Fable 5.1's lead across four benchmarks demonstrate that this remains a round of competition with wins and losses on both sides rather than a one-sided replacement.
Pricing and Speed Remain Unchanged
Grok 4.7 starts at $2 per million input tokens and $6 per million output tokens, identical to Grok 4.6, while maintaining the same inference speed. An official fast version is also available, offering twice the output speed of the standard version at double the price.
This pricing is on the lower end among comparable models. By comparison, GPT-5.6 Sol costs $4 for input and $20 for output at its max tier, while Fable 5.1 costs $10 for input and $50 for output at its max tier. Comparing output unit prices alone, Grok 4.7 is roughly one-third of the former and about one-eighth of the latter.
The practical impact of keeping prices unchanged is manageable migration costs. Teams already using Grok 4.6 can switch models directly in Cursor or Grok Build and run a comparison test with their existing task suites, with no changes required to APIs or invocation methods.
Model Improvements
The reinforcement learning phase for Grok 4.7 also featured longer training times, with the overall difficulty mix of training tasks shifting upward and weight tilting toward problems requiring hours to complete. The official direct result is that the model is better able to check its own outputs and manage long contexts.
Another change occurred in the training objectives. Grok 4.7 was trained to natively understand the Grok Bot harness, delivering better performance in conversational tasks and general knowledge work. SpaceXAI launched Grok Bot on August 11, describing it as a set of continuously running agents, each equipped with its own computer, capable of working within tools and applications.
Document and presentation generation capabilities were highlighted separately. Officially, Grok 4.7 shows marked improvements over Grok 4.6 in both output categories, performing on par with other frontier models.
Scorecard for Seven Benchmarks
Grok 4.7 performs better in creating documents and presentations. In the GDPval and AA Briefcase tests, AI is required to perform the work of professionals such as lawyers, nurses, and financial analysts. Grok 4.7 outperformed Grok 4.6 in both benchmark tests and achieved performance on par with other frontier models.
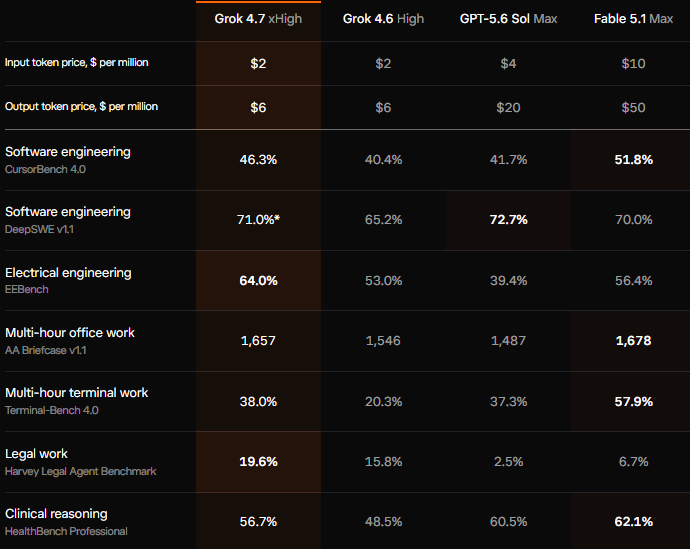
[Official comparison table covering coding, terminal operations, electrical engineering, law, clinical reasoning, and office tasks. Source: x.ai]
Law and terminal operations showed the largest improvements. On the Harvey Legal Agent Benchmark, Grok 4.7 scored 19.6%, the highest in this group, whereas GPT-5.6 Sol scored only 2.5%; on Terminal-Bench 4.0, Grok 4.7 surged from Grok 4.6's 20.3% to 38.0%, nearly doubling. Clinical reasoning improved by 8.2 percentage points, and office task scores increased by 111 points.
The Cost Curve Under Long Tasks
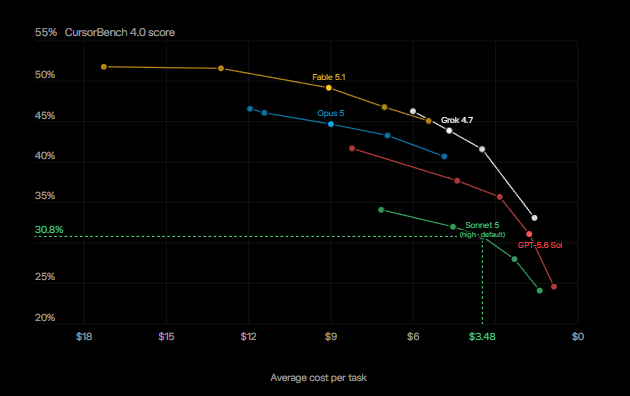
The official page for CursorBench 4.0 presents three charts side by side: average cost per task, average output tokens, and average steps, with the vertical axis standardized to the same set of scores. The reference point in the charts is marked at Sonnet 5 (high default preset): a score of 30.8%, $3.48 per task, approximately 61,000 output tokens, and 85 steps, serving as the baseline for cost-efficiency comparison.
[Source: X.ai]
Looking at the cost curve, Fable 5.1 achieves the highest score, at a cost of nearly $18 per task; GPT-5.6 Sol lies on the low-cost side, with its score dropping more sharply as cost decreases. Grok 4.7 falls between the two, with official claims placing it at the cost-performance frontier on this benchmark. The shapes of the output token and step count charts mirror the cost chart, indicating that cost differences stem primarily from the reasoning length required to complete tasks rather than the unit price itself.
Imagine a six-person backend team migrating a 400,000-line service from an old framework to a new one. Breaking this type of task into single-step commits makes no sense; the model must work continuously for hours and self-check the results of prior steps along the way—the exact scenario CursorBench 4.0 and Terminal-Bench 4.0 seek to measure. Only when the cost per task drops from over ten dollars to a few dollars will a team likely fit it into daily schedules, rather than waiting to process it in batches over the weekend.
Security and Cybersecurity
Grok 4.7 uses an all-new safety stack. Officially, it is described as the company's strongest model tested to date in both refusal rate and jailbreak resistance.
In dual-use domains such as cybersecurity and biosecurity, official data covers both sides: maintaining usability for legitimate tasks while refusing dangerous requests. In biosecurity, Grok 4.7 achieved 62.4% on the LatchBio biosecurity benchmark, the highest score on the benchmark. In cybersecurity, the in-house HackerBench v0.3 benchmark showed that the model allowed only 3.3% of high-risk dual-use prompts, while rarely blocking legitimate security research.
SpaceXAI also stated that it has begun offering invitation-only access to Grok 4.7's red-teaming capabilities to select cybersecurity partners for defensive research.
Nothing in this material constitutes investment advice, personal recommendation, investment research, an offer, or a solicitation to buy or sell any financial instrument. The content has been prepared without consideration of your individual investment objectives, financial situation, or needs, and should not be treated as such.
Past performance is not a reliable indicator of future performance and/or results. Forward-looking scenarios or forecasts are not a guarantee of future performance. Actual results may differ materially from those anticipated.
Mitrade makes no representation or warranty as to the accuracy or completeness of the information provided and accepts no liability for any loss arising from reliance on such information.
Recommended Articles


